Category Archives: Google Summer of Code (GSoC)

Helping Patrons Discover Books

A forward by Mek, Open Library’s program lead:
This year, the Open Library team and I were fortunate to collaborate with Chisom, as part of Google Summer of Code, to make millions of books more discoverable to readers. Chisom entered this year’s Google Summer of Code program a motivated and capable software developer and continued to impress us with her focus, proactivity, and problem solving. It was a joy working with Chisom and rewarding to witness her make consistent forward progress, rise to growth opportunities, and — as a result of hard work and initiative — achieve an excellent outcome that I believe will benefit millions of Open Library patrons. I encourage you explore how she strategically approached this challenge and created a general purpose tool and patterns that will allow others to continue her work into the future.

My name is Chisom Nnamani, and this summer I had the opportunity to join the Internet Archive’s Open Library team as a Google Summer of Code (GSoC) contributor. This was my first experience contributing to a large open-source project, and I could not have asked for a better place to start. As someone who cares deeply about making books accessible to everyone, I was drawn to Open Library’s mission of providing a free webpage where anyone, anywhere can discover and access published works. You can view my initial proposal here.

My GSoC project focused on a problem that sounds simple at first: helping readers find books by genre.

Millions of books available, the challenge is discovery

Over the years, Open Library has accumulated millions of free-form book labels that have never gone through a standardization process. As a result, a book about science fiction might be labeled “science fiction,” “science-fiction,” “sci-fi,” “scifi,” or dozens of other variations. Without a way to recognize and merge these synonyms, books become scattered across hundreds of different labels like a needle in a hundred haystacks.

Search termResults returnedBooks missed vs. best
“Science Fiction”17,900 hits— (baseline)
“science-fiction”16,497 hits~1,421 books
“sci-Fi”2,721 hits~15,179 books

The result shows how a reader can miss hundreds or even thousands of books simply by using a different term to describe the same genre. The books are there. The problem is that the catalogue does not always connect them.

Messy labeling means messy recommendations

The problem goes deeper than the search box. For years, Open Library has used a subjects field to describe what a book is about. These subjects are stored as plain text strings in a flat list, with no consistent rules about how they should be written or organized.

As a result, different kinds of information can end up sitting side by side. A book can have its genre, characters, places, themes, and other descriptions all represented as separate subject strings. There is no structure telling the catalogue how these descriptions relate to one another.

The screenshots below show what this looks like on real book pages. The Hobbit has “Fantasy,” “Fantasy fiction,” and “Juvenile fantasy fiction” as separate tags on the same page:

Figure 1: The Hobbit’s subjects include multiple variants of “fantasy” with no major classification.

The screenshot below shows another example: And Then Were None has over 30 subject tags with no structure distinguishing genre, subgenre, language, audience, character, and other types of information. You can also see multiple variations of “mystery,” including “Mystery fiction,” “Mystery & Detective,” and “Fiction, mystery & detective, general.”

Figure 2: And Then Were None — 30+ subjects with no type distinction between genre, subgenre, language, audience, character.

Together, these examples revealed the larger problem I wanted to address. Open Library had a huge amount of useful information about its books, but it lacked a consistent structure for connecting related genres and descriptions.

That became the starting point for my GSoC project: building a more structured way for Open Library to describe books by genre and subgenre, and eventually using that structure to make browsing and discovery better for readers.

The recipe for organizing 860K books

When I began GSoC, the Open Library team had already identified several high-impact label categories (tag types) that could benefit from this kind of cleanup, including genres and subgenres, audiences, content warnings, and formats. What we didn’t yet have were mappings from our existing messy labels to these new, cleaner categories, or a common software framework that contributors could use to define these mappings and perform the cleanup.

I began by working with genres and subgenres. The first step was to define the categories we wanted to recognize. We then needed to connect the many ways these concepts already appeared in Open Library’s catalogue to a consistent set of canonical labels – the standardized labels we want those variations to map to. For example, different subject descriptions might refer to the same genre using slightly different wording or formatting.

From there, I worked on expanding and refining the mappings so that more of the catalogue’s existing subject descriptions could be connected to the appropriate genres and subgenres.

But the goal was not to build something that only worked for genres. As the project evolved, we built a common core that could support different types of labels through the same process: define a vocabulary, create mappings, analyze existing data, and eventually migrate the cleaned information back into Open Library.

This separation between the tag type and the shared tooling became an important part of the project. Genres and subgenres were the first categories I worked on, but the same framework can be used for other categories as contributors begin cleaning and structuring them.

Here’s what that mapping looks like for a few genres:

Existing subject strings on Open LibraryCanonical genre
“Fantasy”, “fantasy fiction”, “Juvenile fantasy fiction”Fantasy
“Mystery fiction,” “Mystery & Detective,” “Fiction, mystery & detective, general”Mystery
“Science fiction,” “science-fiction,” “sci-fi,” “Science Fiction Literature”Science Fiction

Several different subject strings can now point to the same canonical genre.

Once these mappings were in place, the next step was to give each canonical label a structured representation in Open Library. In the Tags project, a Tag is an Open Library data object representing a defined label, such as a genre or subgenre. This gives the canonical concept its own consistent identity instead of treating every variation of a subject string as a separate concept.

I then created the canonical Tags for the genres and subgenres we had defined.

Fantasy, now represented as a genre Tag in Open Library, rather a plaintext subject string.

Steampunk, a subgenre represented as a Tag.

With the genre and subgenre labels defined and represented as Tags in Open Library, the next challenge was connecting them to the millions of existing works in the catalogue.

Open Library already had millions of works with years of existing metadata. I could not simply assign these new Tags manually to every work. The next challenge was figuring out how to connect the information that was already there to this new structure, and then safely apply those connections across the catalogue.

So I built migration tooling that could analyze existing subjects, identify matches using the genre and subgenre mappings, and connect those matches to the appropriate Tag keys on each work.

Before thinking about millions of records, I first needed to understand what the migration would actually find. I ran the matching process against Open Library’s April data dump, a monthly snapshot of the catalogue’s data, and found 869,461 works with genre matches and 51,526 works with subgenre matches.

Those numbers changed the way I thought about the project. This was no longer just about creating a better vocabulary. It was about applying that vocabulary across millions of works while making sure the information already there was not accidentally changed or lost.

I worked on the migration scripts, the shared utilities behind them, and the changes to Open Library’s work schema needed to store the new genre information. I also validated the migration on a smaller pilot before moving toward the production run.

Safely running a large-scale migration

One of my biggest lessons from this project was that writing the code is only part of the job. When you are changing a large, live system, you have to think about what happens when the code actually runs.

  • What happens if something fails halfway through?
  • How do you know the migration did what you expected?
  • How do you avoid changing records that should not be changed?
  • How do you test an operation that will eventually touch hundreds of thousands of works?

I used dry runs and small pilots before larger operations. I added ways to track progress and designed the migration so that it could be run in controlled batches. Along the way, I also encountered some of the less glamorous parts of working with production systems, from authentication and request limits to unexpected differences in the data itself.

One of my favourite lessons from the project is that production engineering requires trust.

Before you can make a change at scale, you have to earn the right to trust your own tools.

Translating better data into better discovery

In our GSoC project, fixing book labels was always a means to an end: improving how readers discover books. Many patrons come to the Open Library looking for a specific book. But not every reader arrives knowing exactly what they want to read next. With consistent genre data in place, we could begin to ask a different question:

What if readers could browse and discover books by genre instead of having to already have a book in mind?

Search and filtering can help when you already know what you are looking for. But discovery is different. Sometimes you just want to browse.

That question became the idea behind Genre Explorer.

Taking inspiration from Drini Cami’s Library Explorer – a system that uses Dewy Decimal classification numbers to digitally emulate the organized bookshelves of a physical library – we imagined a more visual way for readers to explore the Open Library’s book catalogue, using the same genre and subgenre structure I was building for the tagging project. Instead of presenting genres as another long list of links, we imagined something closer to the experience of walking into a bookstore.

Genres could act as bookcases.
Subgenres could become shelves.

A reader could choose a genre, step inside it, explore its subgenres, and discover books along the way. The idea was to make genre browsing feel less like searching through metadata and more like browsing a library. I developed the initial concept and built a clickable prototype to explore how this experience could work.

From there, Mek and I continued developing the idea together. We reviewed the experience, explored how it could fit with Open Library’s existing components, and refined the concept into an interactive version now available on the testing site.The interactive version follows the same idea: genres act as bookcases, and entering a genre reveals its subgenres as shelves.

What I find most exciting about Genre Explorer is that it grew out of the original tagging problem, but takes the idea one step further. The canonical Tags give Open Library a consistent way to describe books. That structure can support better search and filtering, while Genre Explorer explores what it could look like when the same information is used to help readers browse.

It was an unexpected direction for my GSoC project. I came in focused on the data and infrastructure behind genre information. Along the way, I started thinking beyond how books are described to how that work could become something a reader actually experiences.

Takeaways

When I started this project, I expected to learn more about software engineering. I did, but not always in the ways I expected.

One of my biggest lessons was learning to slow down and understand a system before trying to change it. I learned to look at messy data and find the patterns hidden inside it, to test my assumptions against real examples, and to treat small experiments as part of the engineering process rather than as steps before the “real” work begins.

I also learned to think beyond the implementation. Throughout the project, I kept coming back to a simple question: Does this actually make the experience better for the person using it? That question shaped how I thought about the tagging system, and eventually led to the idea of Genre Explorer. It reminded me that good engineering is not only about building something that works. It’s also about understanding if and why something should exist in the first place.

Working with Open Library also gave me my first real experience contributing to a large open-source project. I had to learn how to navigate an unfamiliar codebase, communicate ideas clearly, ask questions when I was unsure, respond to feedback, and make decisions when there was no obvious answer. I was not doing this work in isolation. My mentor, Mek, pushed me to think beyond the code and focus on the larger problem we were trying to solve. Open Library contributors and maintainers, including Jim, Drini, Liz, and Katrina helped me understand different parts of the systems I was working with. Every review, discussion, and debugging session became part of the learning process.

Looking back, I think that may be one of the most valuable things I am taking away from GSoC: learning how to become useful in a system that existed long before I arrived.

Next steps

By the end of GSoC, we were able to add genre tags to more than 50,000 works. We also built common infrastructure to standardize the tag migration process and enable others to contribute to the greater cleanup process.

The next stage is to extend this process to add subgenre tags to works and to index these genre and subgenre tags in Open Library’s search engine, so readers can find and explore books by genre.

Genres and subgenres are only the beginning. Open Library has other high-impact label categories that will benefit from the same approach, including audiences, moods, content warnings, and content formats. Because we built this project to have a shared core for defining vocabularies, creating mappings, analyzing existing data, and migrating cleaned information, future contributors can use the same tooling to work on these categories rather than building a new system from scratch.

This shared core is the legacy I hope will last beyond this GSoC project: not just cleaner genre and subgenre data, but a reusable foundation that makes it easier for Open Library and its contributors to continue turning messy catalogue labels into structured information that can improve how readers discover books.

Google Summer of Code Contributors Improve Open Library’s Patron Experience

This year, as part of Google Summer of Code (GSoC), the Internet Archive is collaborating with two outstanding contributors to make it easier for patrons to find relevant books on Open Library.

Tanishq Sangwan, a 19-year-old from Gurugram, India, and Chisom Nnamani of Lagos, Nigeria, are two of 1,141 software developers from around the world who have been selected through GSoC to hone their engineering capabilities with open-source organizations.

“The Internet Archive’s focus for 2026 is: tools for participation. Participation must be earned by building an experience patrons want to return to.” said Mek, program lead for Open Library. “The work that both Chisom and Tanishq are doing is central to creating a more reliable Open Library experience, where readers can repeatedly discover, access, and enjoy books.”

Sangwan, who just completed his second year of college studying artificial intelligence, is focusing on the journey of patrons who join Open Library and use it once, but do not return. His objective is to understand where patrons encounter barriers and identify opportunities to create a more useful, lasting experience.

Sangwan, who just completed his second year of college studying artificial intelligence, is focusing on the journey of patrons who join Open Library and use it once, but do not return. His objective is to understand where patrons encounter barriers and identify opportunities to create a more useful, lasting experience.

Sangwan comes into the project with two years of experience from ZNotes, an educational organization that provides free notes and videos from students around the world.

“I built this passion and got this amazing feeling when my work was making an impact on people and they were receiving some value,” he said. “Now, Google Summer of Code is a wonderful opportunity to connect with open-source organizations and Open Library where its work directly impacts people’s lives.”

“This year’s collaboration is important because lots of patrons discover Open Library, but too often don’t always find the books they want,” Mek said.

The work begins when a patron lands on a book that is unavailable for reading. Soon, instead of reaching a dead end, patrons will be presented with nearby books on the same shelf that are available now.

When patrons find a relevant, available book, a simpler registration process will help them get started with fewer steps and return to the book they found. Furthermore, Sangwan is helping patrons connect with new book recommendations on an ongoing basis by introducing an activity feed to the account page.

“I like to hear about the patron psychology, how they’re interacting with the platform, and what’s going in their mind from the first moment to the very last,” he said. “We’ll be researching and conducting interviews with lost patrons so we can connect this bridge between patrons and the millions of books in our catalog.”

Chisom Nnamani
Chisom Nnamani

Nnamani, who already has certifications in Data Analytics and Data Engineering, just completed her sophomore year pursuing a second degree in Computer Science. At Open Library, Nnamani is leading a major cleanup effort to add structured tag data to books so they can be searched by genre and subgenre. Her work is paving the way for the addition of a wide variety of new searchable tags, including: moods, fiction and non-fiction, content warnings, and literary formats, such as memoirs, biographies, and more. By cleaning up messy data and enabling better genre and subject browsing, Chisom is helping remove barriers preventing patrons from discovering books they love.

“Today, many of our subject pages feel computer generated and can’t compare to the beautiful, curated experiences you find at small book stores,” says Mek. “The work Chisom is leading to map the messy subject tags we have to clear genres and subgenres will help us offer patrons a more useful and satisfying browsing experience.”

“I really care about books being accessible to people,” Nnamani said. “In Nigeria, we have limited access to physical libraries, so Open Library is something that matters. It gives everyone the opportunity to come and read any kind of book and gain insights.”

“This project is inspiring to me,” Nnamani said. “I like to work on projects where I can connect the data and infrastructure in ways that contribute to the organization’s goals. I enjoy helping to solve complex problems at the intersection of systems and data.” 

Open Library Fellows work remotely, but meet regularly online with Internet Archive staff and mentors. At the end of the summer, each contributor will publish a blog post explaining their technical journey and experience gained.

Since 2005, Google’s Summer of Code has supported more than 23,000 students from 123 countries with stipends to receive mentorship and contribute 48 million lines of code to over 1,000 open source organizations worldwide.

Sandy Chu: My Internship at the Internet Archive

This summer, continuing a years-long tradition, Open Library and the Internet Archive took part in Google Summer of Code (GSoC), a Google initiative focused on bringing new contributors into open source software development. This year, I was lucky enough to mentor Sandy, a long-time Open Library volunteer, on an exciting project to increase the accessibility of our books with real-time translations. We have invited Sandy to speak about her experience here as we reach the culmination of the GSoC period. It was a pleasure getting to work on this exciting project with you Sandy! – Drini

My name is Sandy Chu and I am a 2025 Google Summer of Code (GSoC) candidate who had the opportunity to work with the amazing Internet Archive engineering team. Prior to participating in the GSoC program, I had contributed as a volunteer software engineer for the Open Library open source repo. As someone who grew up using local libraries as a place to supplement my education and read books that my school could not afford, I was drawn to the Open Library’s mission to empower book lovers and provide a free, valuable resource to all. You can view my initial proposal here.

Coming soon in September, the Open Library will be able to better serve its global audience to access books that were previously not available due to a lack of localization. With the help of open source projects such as the Mozilla Firefox Translation Models and Bergamot Translator library, a new BookReader plugin will have the ability to leverage a user’s browser and hardware resources to toggle translations from a book’s original language to a translation in their language. Additionally, the translated text will also work with the ReadAloud feature to read books in the translated language.

The “Real-Time In-Browser Book Translation w/ Read Aloud (TTS)” project closely aligns with the Open Library’s 2025 goal of providing more with less. Although the Internet Archive hosts and provides its patrons with hundreds of thousands of publicly available works, patrons are limited to a subset of works that were published in their native language. Due to the unique image based implementation of the BookReader application, default browser translator options are not viable for many readers, so this project presents an opportunity to make a big impact for international audiences.

Currently in internal beta, the translation plugin allows patrons to quickly initiate a local translator on-their device and translate the book’s text in just a few seconds per page. With nine distinct languages available for translation from English (and potentially over 40 as we update to Mozilla’s latest models), this project will make countless works more accessible for patrons.

The primary goals of this project were:

  • Translating a book’s original text content to the patron’s desired language with minimal delay or disruption
  • Creating a visually seamless experience to maintain the immersive experience of reading a book without having to go back and forth between a translator and the book
  • Redirecting the existing TTS plugin to use the translated text when the BookReader is in translation mode

Language

Total Readable Books on OL

% of All Readable / Borrowable Books (out of 4,526,060)

Native Speakers Globally

(in millions)

English

3,034,445

67.04%

390

French

332,052

7.33%

74

German

180,341

3.98%

76

Spanish

120,516

2.66%

484

Chinese

90,531

2.00%

1,158

Korean

5,384

0.11%

81

Arabic

2,415

.000533%

142

Retrieved from Wikipedia, which references Ethnologue as its source. Chinese and Arabic dialects are grouped together since they both have a unified written system.

Translations

At the center of the translation plugin are the Neural Machine Translation (NMTs) models provided by Mozilla Foundation’s Firefox Translation Models project. These files contain the lexical and vocabulary conversions from the original language to the target language; these compact models are essential to the real-time, browser-side aspect of this project. Since we are currently using an older subset of models, the translation feature is still considered in the “alpha” stage of maturity and accuracy.

When the translation plugin is enabled by the user, the language registry and model files are fetched from a server within the Internet Archive. After the models have successfully loaded into the user’s browser, we are able to use the Bergamot Translator project scripts to create a dedicated Web Worker, which is initialized to handle the translation tasks in a separate background thread. The Web Worker immediately retrieves the text content within the text selection layer for the currently visible page(s) for translation. Pages that have been rendered but not visible in the BookReader are given a lower priority and translated after the queue of visible content is completed. 

An unmodified page in the BookReader.

The translation plugin script feeds the text within the text selection layer into the model for processing and prepares the stage for the translated output by covering the original image and text selection layer with a beige background. [Pull Request #1410]

The translation plugin has initialized and is providing the original text to the language model.

Once the translation is completed by the dedicated Web Worker, the output is then used as the text content for its respective paragraph chunk and appears as if the work is actually written in the target translation language.

The translation has completed and is now on the page!

Images with captions are also carefully handled so that the translated text box occupies nearly the same space as the text selection layer itself. 

Each translated paragraph is stored in a cache with a unique key to prevent the browser from re-translating recently viewed content [Pull Request #1410/commit]. To prevent readers from having to wait for the translation when “flipping” to the previous/next page, the translation plugin targets the visible pages on the screen then works to complete the translations for the non-visible but loaded pages. If a user decides to flip far from their current page in the work, the translation plugin will detect the newly rendered page and translate / populate the translated text layer while adjusting to a new page on the fly.

The text selection layer has been adjusted to appear in red.
The translation layer occupies roughly the same height and width by copying the text selection layer’s properties.

Fine-tuning the visual presentation and behind-the-scenes functionality of the plugin were the main challenges for this portion of the project. Ensuring that the translations for each text chunk were done without depending on a previous chunk was an essential behavior we identified in the early stages of the project. Both asynchronous and synchronous behavior is implemented within the code to ensure that users do not have to wait for longer than needed for paragraphs to complete their translations. The translation plugin utilizes event listeners within the BookReader to detect when a newly rendered text layer is created, which then triggers a translation call to the text content from the upcoming page.

Styling the translated text layer also proved to be difficult. Although it is possible to reuse the style properties on the existing (and invisible) selection text layer, additional adjustments were needed to ensure that the visible translation text would not overlap or go beyond the bounds of the original paragraph. In the early phases of the translation plugin development, there were many instances of text chunks exceeding the boundaries set for the translation layer, which resulted in scrollbars appearing within paragraph elements or not aligning properly with the text on the page.

A screen capture from an earlier version of the translate plugin. A scrollbar can be seen in the 2nd paragraph element of the left page.

Another styling issue that caught us off guard was a pre-existing bug that was only visible in the Chrome browser. Since Drini and I were both using Firefox as our default browser, we later learned during a demo that there was an element scaling issue that was immediately visible when the translation plugin was activated. [Pull Request #1421/commit]

ReadAloud

The next major piece of this project was to connect the translation plugin to the ReadAloud feature and allow users to hear the translated text read aloud. 

The normal flow of the TTS (Text-to-Speech) plugin calls a server-side API to retrieve chunks of text and bounding rectangles based on the page and paragraph index. However, since we have the translated text available within the BookReader locally, the extra network calls to the server were dropped in favor of feeding the translated text lines into the TTS engine directly. Tweaking the pre-existing functionality of the TTS plugin to interact with the content generated by the translate plugin required a substantial amount of investigation to figure out where the adjustments needed to be made for the translation plugin to gracefully take over. 

When the TTS plugin is activated, it checks whether or not the translation plugin is enabled within the BookReader. If the translation plugin is active, the TTS plugin retrieves the translated text on the page to use as its text input for the voice engine. 

Voice overs are also automatically adjusted as soon as the TTS begins to streamline the reading process. By checking the source language from the work’s metadata, the default voice of the TTS reader is automatically adjusted to the target language that was set within the translate plugin. The voice menu is also re-rendered to allow users to more easily switch between the source, target, or other languages for the TTS reader. [Pull Request #1430/commit]

ReadAloud Menu
The ReadAloud voices menu as it is seen without the translation plugin activated.
ReadAloud Menu With Translation
Voices are categorized by the source language, target language, and other languages detected on a user’s system.

Visual parity between the original TTS and translated TTS was maintained as well by highlighting the entire translated paragraph section. Since network info containing the bounding rectangles for a text chunk were no longer available, I was able to use a paragraph element’s offset properties to highlight the text being actively read by the TTS reader [Pull Request #1431/commit].

The BookReader highlights chunks of text that are actively being dictated by the ReadAloud plugin.
ReadAloud highlight with translation active
With a few tweaks, the ReadAloud highlighting feature can also be used to highlight the translated text being dictated by the voice over.

Although this stage of the project did not require as much new code, we encountered a relatively complex issue that would cause the TTS reader to not progress if the translation plugin is activated in a part of a book that contained one or more blank pages. The translation adjusted implementation of the TTS plugin would wait for a new page to be loaded and rendered within the browser but remain stuck on a page due to a synchronization issue. After two weeks of extensive investigation and testing, we were able to resolve the issue by utilizing an existing method that returns all pages that have been loaded but not rendered in the DOM yet [Pull Request #1431/commit] and consolidating the asynchronous translation call with Promise.all().

Next Steps

For now, this feature is currently scheduled to be released for internal testing before being released for full public use. While the majority of goals were completed within the project timespan, there are many additional improvements and expansions that are planned in the future as the BookReader’s translate plugin becomes more mature. The next major steps for this project involve expanding the number of available translation pairs by integrating the latest models from Mozilla’s Translation Model project, receiving and implementing feedback from a round of internal testing, and continually improving the UI of the plugin. Unit tests and offline testing environments are also part of the project’s future goals to help improve the troubleshooting process for developers.

Conclusion

I would like to express my thanks once again to my GSoC mentor Drini for his guidance. The first few weeks of this project felt especially daunting, but the patience and advice that I was given throughout this program helped me realize that this big intimidating project was easier to manage as a number of small tasks were taken step-by-step. I am very glad that I had the chance to be challenged in new ways while being able to leverage my existing JavaScript skills. 

I am extremely grateful that I was able to participate in the GSoC program and to help contribute to a high-impact feature for both the Internet Archive and Open Library. Though my time as a GSoC contributor has officially ended, I intend to continue my work as a contributor with the Open Library team to expand on the functionality of this feature and help increase the availability of published works to a wider global community.

Bringing Sidewalk Libraries Online

by Roni Bhakta & Mek

All around the world, sidewalk libraries have been popping up and improving people’s lives, grounded in our basic right to pass along the books we own: take a book, leave a book.

As publishers transition from physical books to ebooks, they are rewriting the rules to strip away the ownership rights that make libraries possible. Instead of selling physical books that can be preserved, publishers are forcing libraries to rent ebooks on locked platforms with restrictive licenses. What is a library that doesn’t own books? And it’s not just libraries losing this right — it’s us too.

⚠️ Did you know: When a patron borrows a book from their library using platforms like Libby, the library typically pays each year to rent the ebook. When individuals purchase ebooks on Amazon/Kindle, they don’t own the book — we are agreeing to a “perpetual” lease that can’t be resold or transferred and might disappear at any moment. In 2019, Microsoft Books shut down and customers lost access to their books.

This year, Roni Bhakta, from Maharashtra, India, joined Mek from the Internet Archive’s Open Library team for Google Summer of Code 2025 to ask: how can the idea of a sidewalk library exist on the Internet?

Our response is a new open-source, free, plug-and-play “Labs” prototype called Lenny, that lets anyone, anywhere – libraries, archives, individuals – set up their own digital lending library online to lend the digital books they own. You may view Roni’s initial proposal for Google Summer of Code here. To make a concept like Lenny viable, we’re eagerly following the progress of publishers like Maria Bustillos’s BRIET, which are creating a new market of ebooks, “for libraries, for keeps“.

Design Goals

Lenny is designed to be:

  • Self-hostable. Anyone can host a Lenny node with minimal compute resources.
  • Easy to install. A single https://lennyforlibraries.org/install.sh install script uses Docker so Lenny works right out of the box.
  • Preloaded with books. Lenny comes preloaded with over 500+ open-access books.
  • Compatible with dozens of existing apps. Each Lenny uses the OPDS standard to publish its collection, so any compatible reading app (Openlibrary, Internet Archive, Moon reader and others) can be used to browse its books.

Features

Lenny comes integrated with:

  • A seamless reading experience. An onboard Thorium Web EPUB reader lets patrons read digital books instantly from their desktop or mobile browsers.
  • A secure, configurable lending system. All the basic options and best practices a library or individual may need to make the digital books they own borrowable with protections.
  • A marketplace. Lenny is designing a connection to an experimental marketplace so one can easily buy and add new digital books to their collection.

Learn More

Lenny is an early stage prototype and there’s still much work to be done to bring the idea of Lenny to life. At the same time, we’ve made great progress towards a working prototype and are proud of the progress Roni has achieved this year through Google Summer of Code 2025.

We invite you to visit https://lennyforlibraries.org to learn more about how Lenny works and how you can try an early prototype on your personal computer.

Google Summer of Code 2023: Supercharging Subject Pages

Hello, I am Jayden Teoh, a student from Singapore, and this year I participated as a 2023 Google Summer of Code contributor with the Internet Archive’s Open Library project to improve the site’s performance and supercharge subject pages.

If you are an Open Library patron, you have likely encountered times where certain pages seem to take and eternity to load. The Open Library team understands the importance of a smooth browsing experience and empathizes with how degraded site performance affects patrons. This is why we prioritized site performance as a key focus for our 2023 GSoC roadmap. As strongly as we felt about improving the core performance of the current website, we also wanted to push the boundaries of Open Library’s capabilities by releasing community-powered subject pages we hope will help patrons more easily showcase and discover books they’ll love. I’m excited to share more about what we accomplished and next steps in our plans.

Improving Site Performance

According to Browserstack,”40% of visitors will leave a website if it takes longer than three seconds to load”. But how do we measure which pages are slow or fast? How do we determine if a slow load time is an anomaly or a systemic pattern? Do we care about improving the average load time for a page or eliminating the most egregious case where pages load especially slowly?

Identifying site performance issues can be a challenging task. In order to effectively address this issue, Mek, a GSoC mentor for the project, suggested the use of performance tracking tools such as Sentry, as well as considering Google’s Core Web Vitals metrics, using Google’s PageSpeed Insights (PSI) reports and running Lighthouse audits.

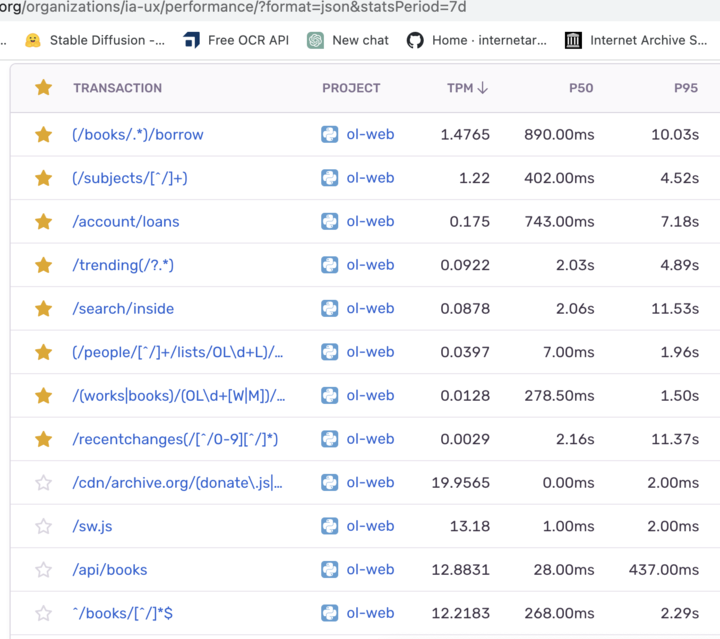
Sentry, a visual dashboard often used for error monitoring, has a “Performance” mode we were able to use to identify and rank pages according to metrics called P50 and P95 — the upper bound number of seconds at which 50% (P50) and 5% (P95) of transaction took to complete. For example, a P95 score of 5 seconds tells us that 95% of such requests completed within 5 seconds (and perhaps 5% were slower). Once we ranked pages in consideration of these metric, it became clearer just how bad certain pages could be in worst case scenarios. We coupled this information with our own domain expertise about which pages are most important to the average patron’s experience and then embarked on a journey with the aspiration of reducing the average load time of key pages by at least half.

For each row in Sentry’s performance dashboard, one can “drill in” to the page to see stack tracebacks and detailed breakdowns about which functions were participating most to the slow response.

Our research revealed 2 opportunities:

  1. The “Search Inside” page was taking more than 11 seconds and an average of more than 2 seconds because the response was making redundant archive.org metadata request on each search result match on the page to determine each book’s availability, rather than computing the availability of all the books in a single request.
  2. Several of the slow pages had a common slow component — the LoanStatus borrow button — which we could speed up by caching and thus “feed two birds with one scone”.

By the end of the 12 weeks of this program, we manage to reduce the load times of several key pages significantly. One of my proudest achievements was the reduction of the ‘search/inside’ page by over 500%. This feature is important to patrons because it allows them to search for content within books, rather than just searching based on the author and title so I am glad we were able to make this feature faster and thus more accessible.

Editor’s note: We are still collecting metrics and plan to add before-and-after graphs of the search inside page speeds. Our changes to the borrow button are in the process of being staged and tested and we’re excited to update this blog post with metrics in the future. Hopefully you have noticed the improvements since it was launched a few weeks ago!

Unleashing the Power of Subject Tags

Empowering Librarians and Expanding Book Categorization at Open Library

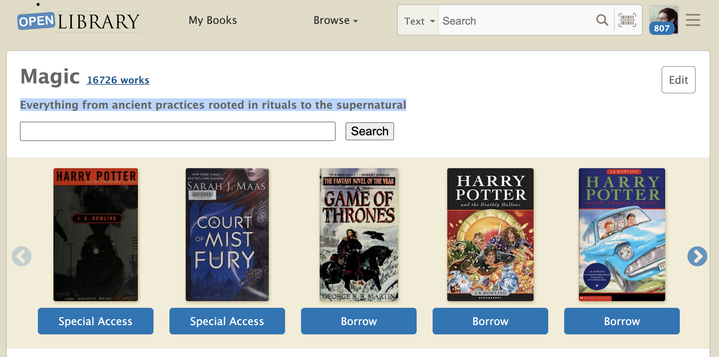
For almost a decade, the Open Library has had basic subject pages that give readers a way to browse or search for books on a given topic, see books with similar subjects, and discover prolific authors of a genre. It may surprise you to learn that the whole page experience is generated based on the name of the subject. For instance, when one visits the “Magic” subject page, one may notice a carousel of books that is populated using a query based on its name: “subject:magic“. This approach gives us a simple formula for creating millions of subject pages on-the-fly, but it also has significant shortcomings.

Namely, subject pages are incapable of storing additional metadata about a given subject and the current subject pages is limited to showcasing a single carousel of books. If the subject is overly vague, like “textbooks“, the reader may often not be shown a useful set of books and there’s no affordance provided that helps the reader narrow their search further, e.g. to design textbooks. If we search for a subject called “design textbooks“, we are informed no matching subjects exist. However, if we do an intersecting search for books that are subject:textbooks AND subject:”industrial design”, there are a few interesting results! The problem is, there’s currently no mechanism which allows librarians to extend Open Library subjects and specify which book collections should show up.

My primary objective through GSoC was to give librarians the ability to enrich and edit any subject page on Open Library so each page may be as beautiful and thoughtfully curated as a library or bookstore showcase. Our solution was to give librarians the ability to create a new “Tag” document for any subject page and load it with custom logic to extend how that subject page should be rendered. Tags serve as a catalyst for librarians to provide more precise categorizations within broad subjects. By leveraging Subject tags, librarians can dive deeper into specific areas of interest, allowing readers to discover a rich array of sub-subjects. For instance, librarians might choose to add new rules into the Tag document for the Cooking subject featuring carousels for vegan and budget cooking, in order to make it more useful for readers. This granularity opens up a world of possibilities, enabling readers to explore their preferred niches and discover hidden gems within subjects they cherish. Just like how a physical library may rotate their bookshelves with new categories every month, Subject Tags grant librarians more freedom to curate interesting subject topics that may suit patrons, allowing for a more personal and humane touch to the book discovery process.

By now, I hope you are able to understand just how pertinent Subject Tags will be to our Open Library and why it is a privilege for me to be working on such an important feature. Although the idea is clear, the implementation certainly is not. Open Library’s database is built using our own niche and complex Wiki engine called Infogami. To create a new class of data, we would have to create a new Infogami type. Here’s the catch: there has not been a new Infogami type created in the last 13 years and there is no existing documentation for doing so. Navigating any new code architecture can be a tedious task for any programmer and now I had to miraculously work with an arcane technology that no one knows how to use? What could go wrong?

Thankfully, I had the support of a wonderful community and amazing mentors like Mek, Jim, and Drini. They provided me with a lot of guidance throughout the process of reverse engineering the creation of an Infogami type. And after months of work, I was able to successfully incorporate a new Subject Tags Infogami type into the Open Library architecture. Especially since Open Library is an open-source project, I decided to write a tutorial and document the unintuitive technical aspects of implementing a new Infogami type, as a gift to help future developers who may wish to extend the functionality of the platform in similar ways. The tutorial can be found here.

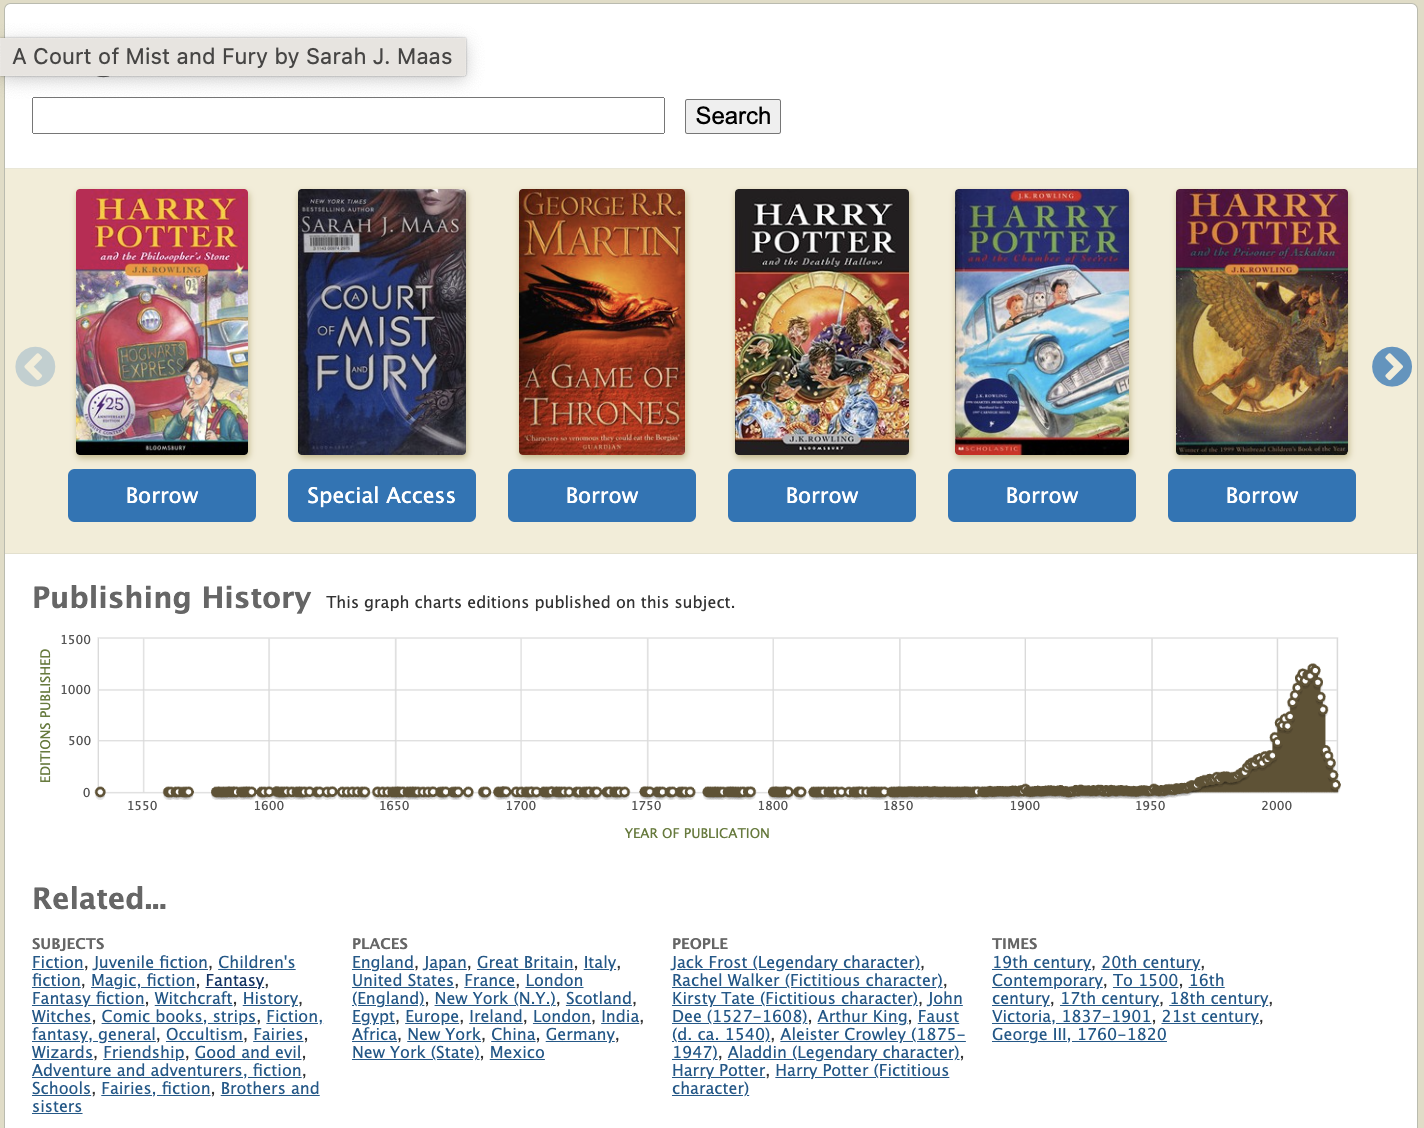
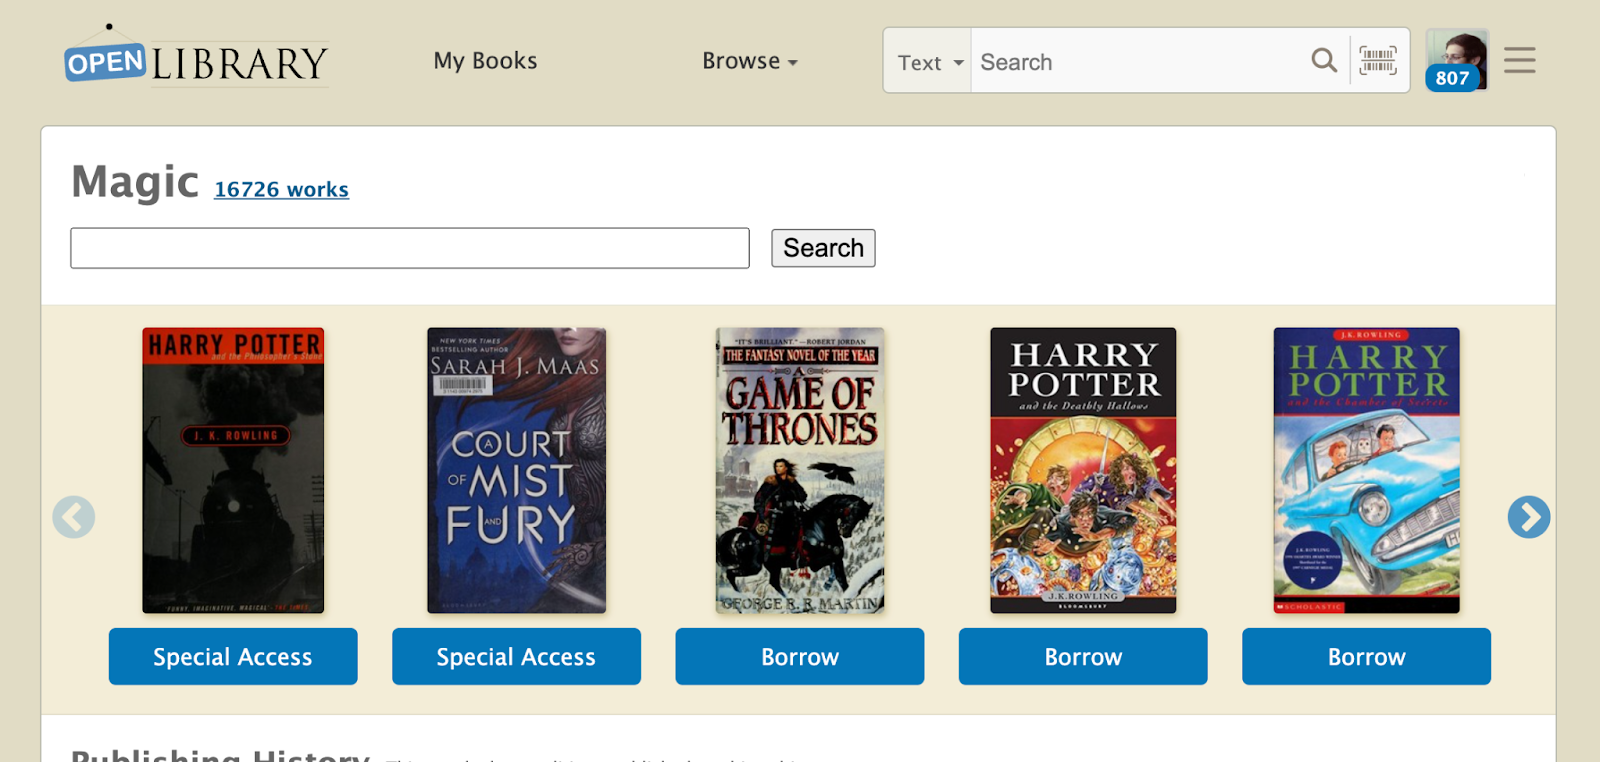
Now, let me show you the power of Subject Tags and how they can be used to enrich the Open Library’s Subject pages. Let’s use the ‘Magic’ subject page as an example. This is how it looks right now.

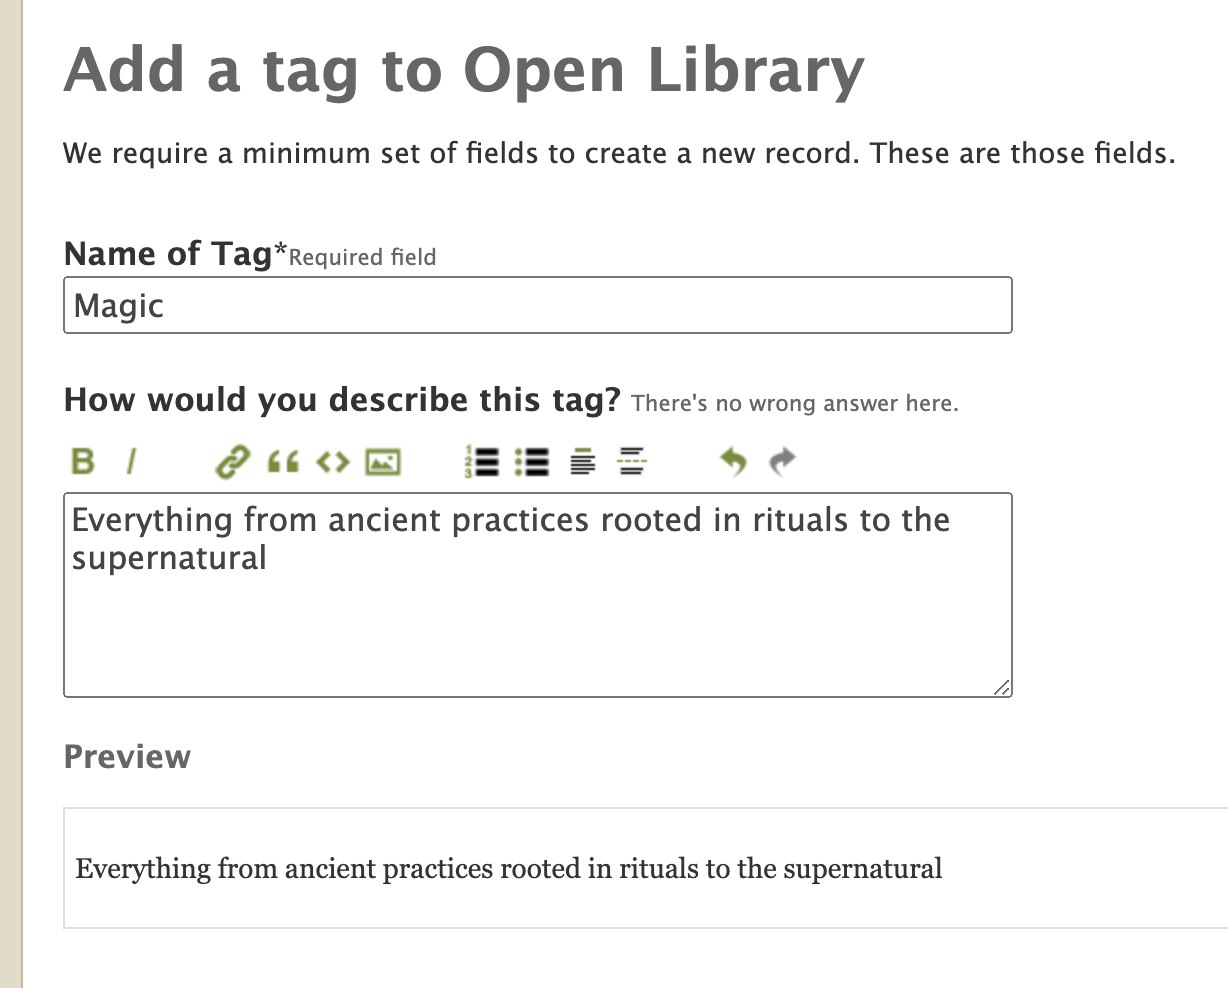
As you can see, currently the subject page is plain with no description about what the subject is about. That’s not very informative is it? Prior to Subject Tags, we are unable to store more information about subjects because they are just strings with no capabilities to store other metadata. However, now with the Subject Tags, we can do that! Let me show you how. First, let’s add a new Subject Tag into the Open Library for the ‘Magic’ subject.

The Subject Tag creation form allows us to store metadata about the ‘Magic’ subject, including its description. After we’ve created the Subject Tag, let’s head back to the ‘Magic’ subject page. Tada, we can now see the newly added description in the subject page.

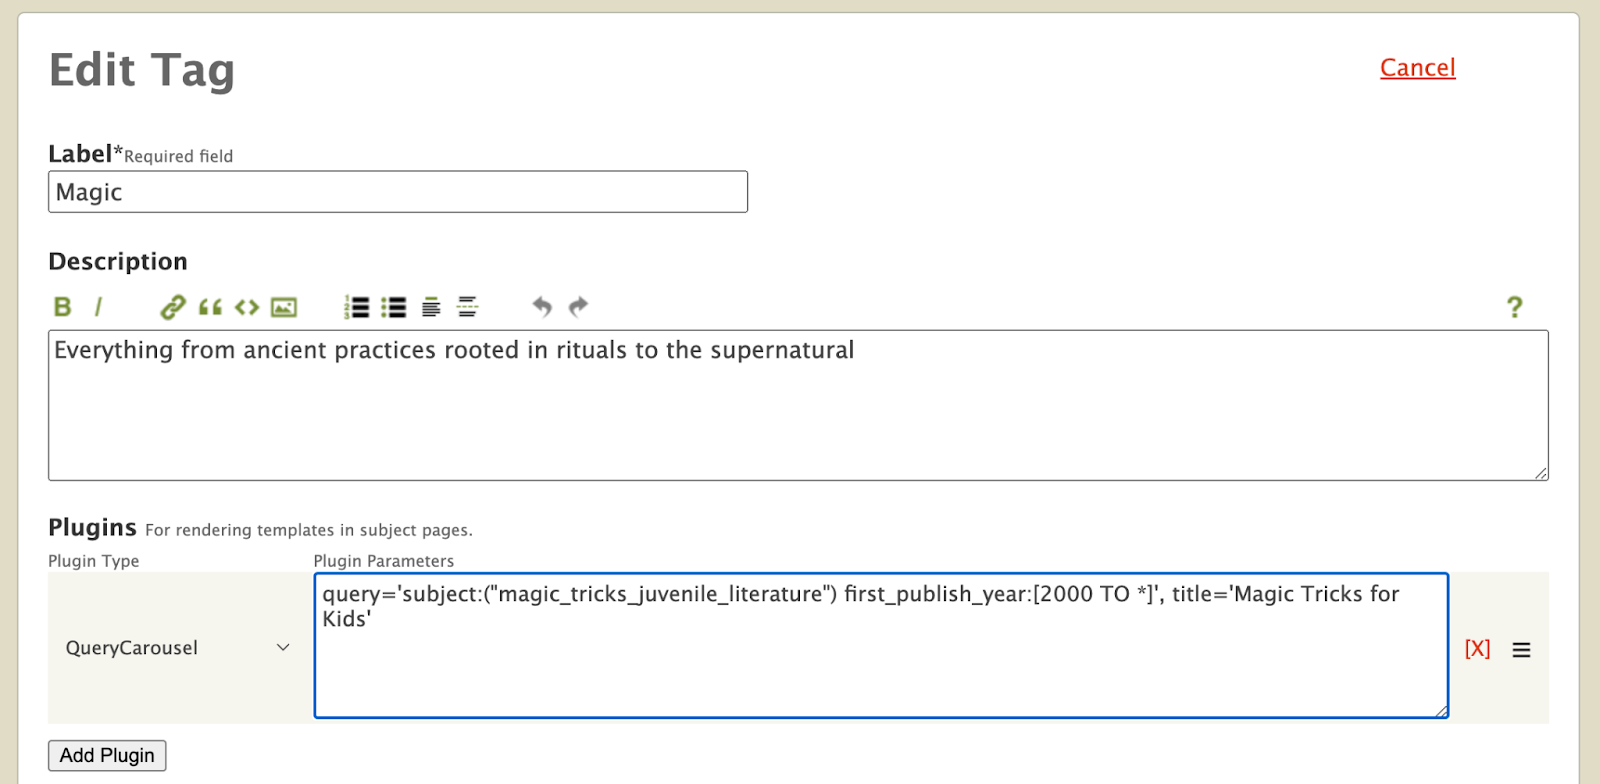
You are probably still not convinced of the utility of Subject Tags. Let me give you a deeper glimpse into the realm of possibilities that Subject Tags offer. Currently on the Magic page, we are only able to display a carousel with books that have the subject ‘Magic’. What if we want to include a carousel displaying books about ‘Magic Tricks for Kids’? Well, with Subject Tags, now we can! As a librarian, we can edit the ‘Magic’ Subject Tag and use the experimental Plugin to define a new carousel. Right now, the interface is quite advanced, is still being prototyped, and is intended for expert librarians who know how to compose queries, but in the future we aim to make it easy for any librarian to extend the functionality of subject pages using Tags.

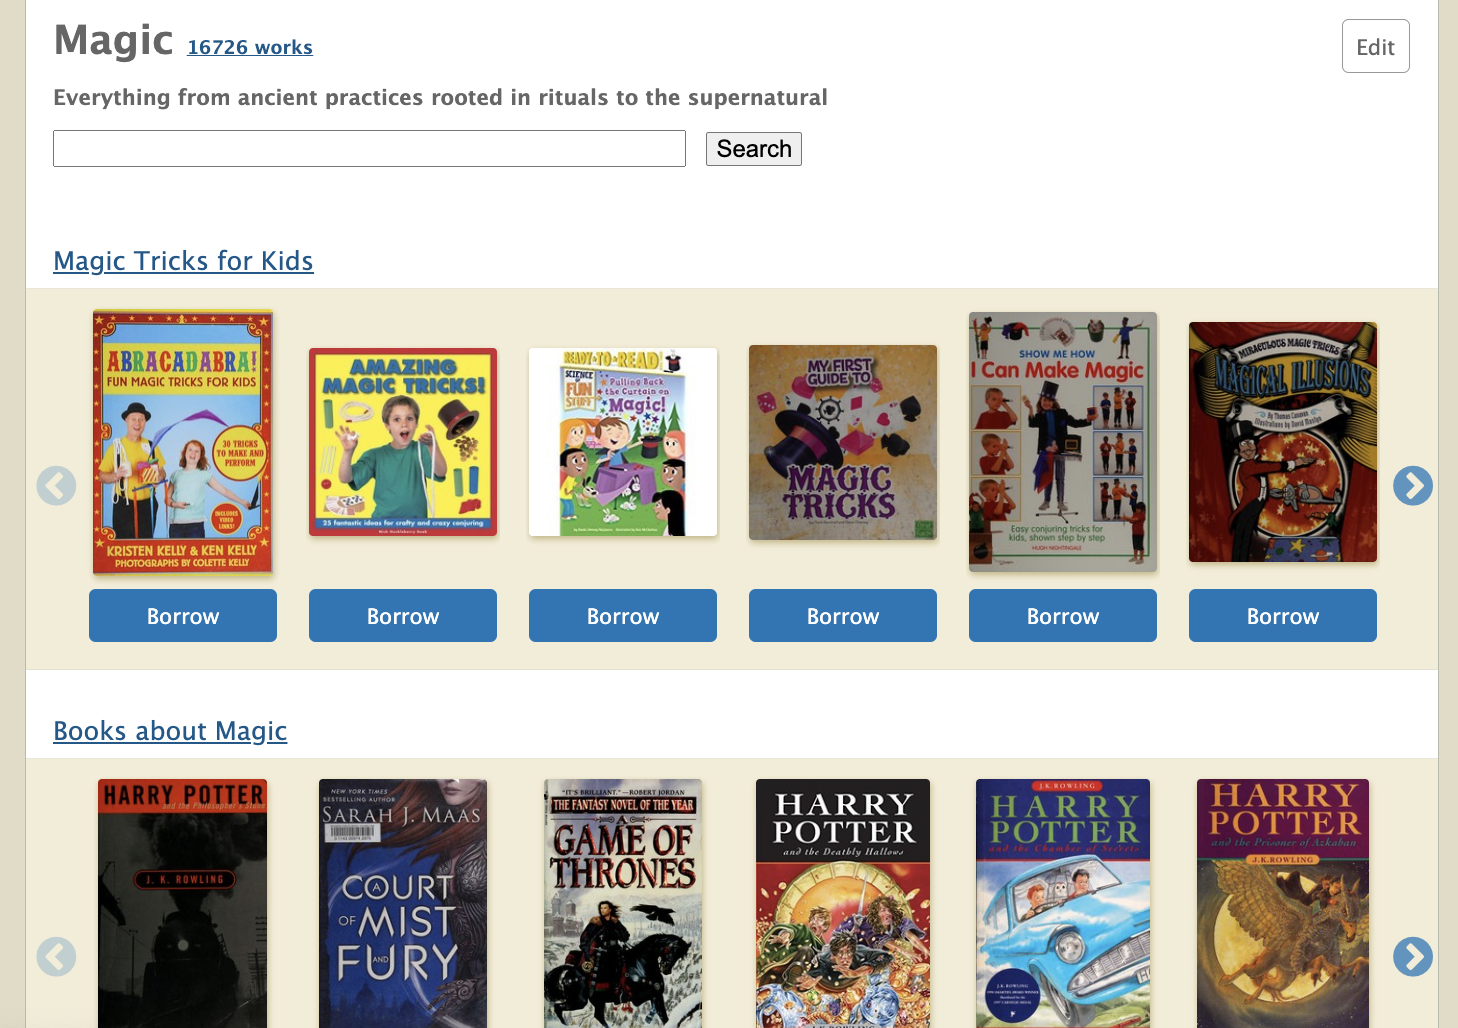
Plugins allow subject pages to load custom templates within our system and utilizes them to enrich the subject page. For example, in the Plugins field of the Subject Tag edit form above, we included a new QueryCarousel Plugin that allows the ‘Magic’ subject page to search for all books with the “magic tricks juvenile literature” subject and display them in a template carousel. Let’s take a look at the ‘Magic’ subject page again. 

Fascinating isn’t it? Subject Tags have enabled the enhancement of the previously one-dimensional subject pages. Through Subject Tags, librarians are now equipped to curate and display information that can enrich the book discovery experience of patrons.

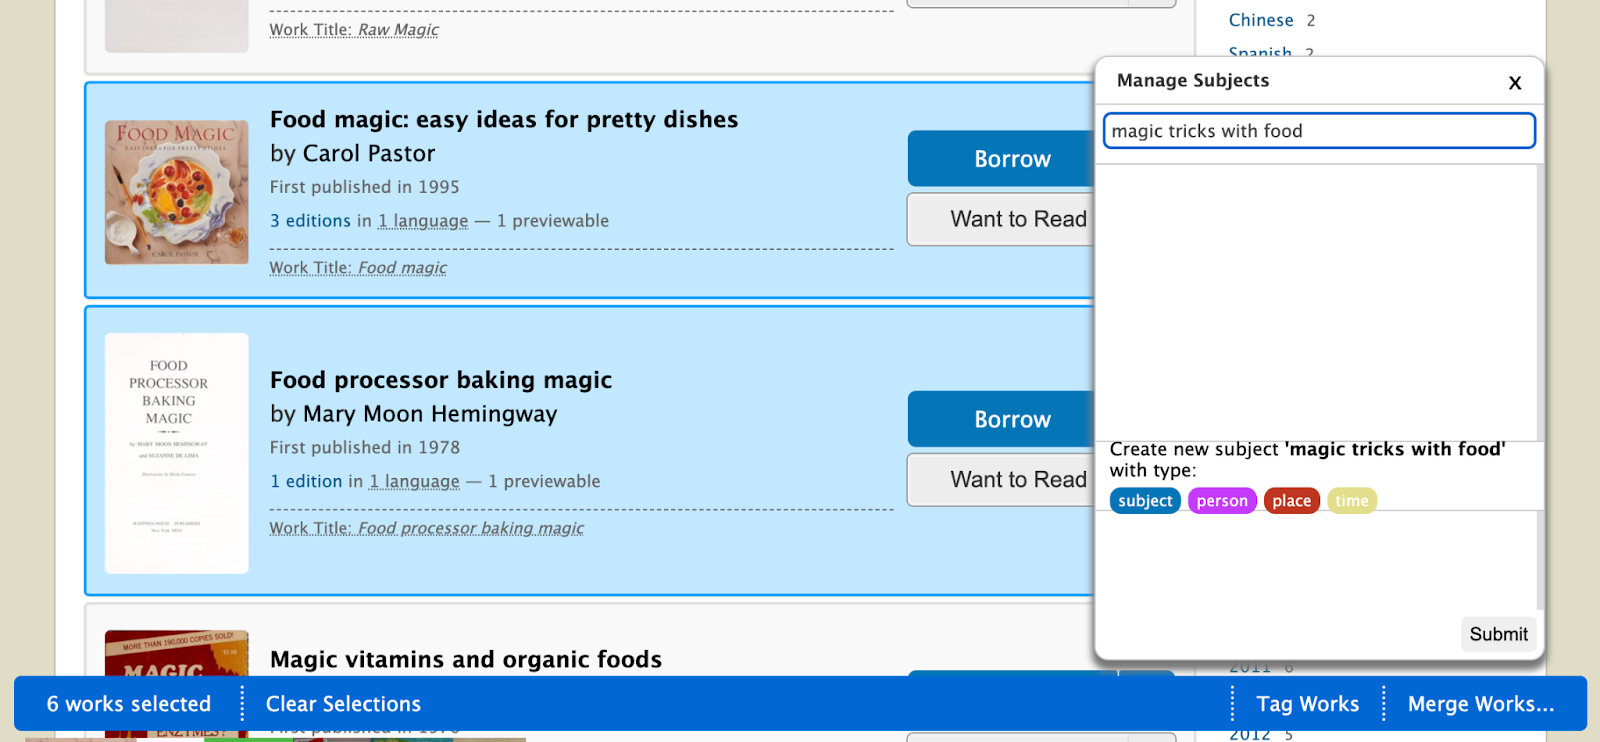
What happens when librarians want to add a new carousel of books to a subject page but the books haven’t been labeled with subjects? When we developed the Tag feature, adding a subject to books had to be done one book at a time. To aid librarians in the process of curating books and subjects, I also implemented a Bulk Tagging tool that enables librarians to add subjects to multiple books simultaneously. 

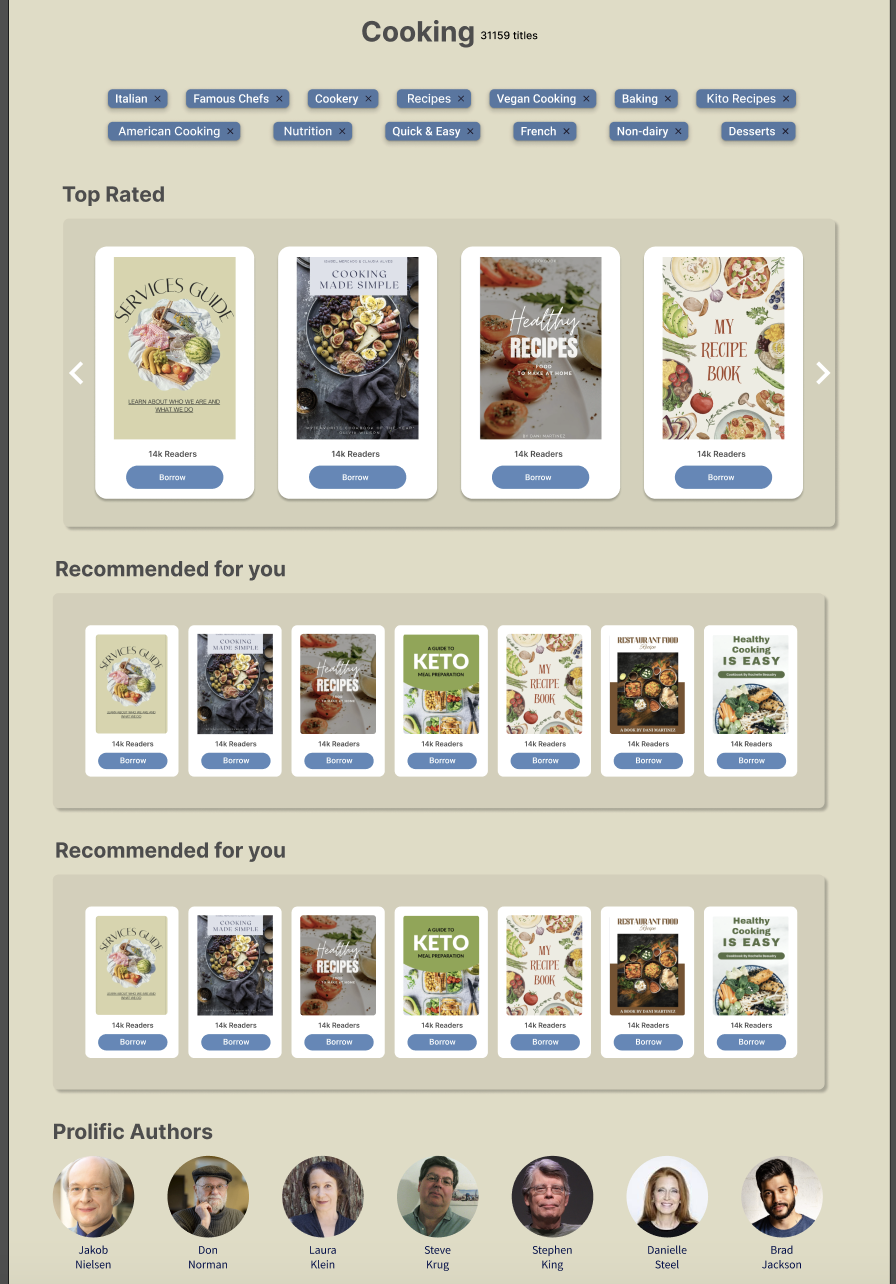
Subject Tags are still in beta so we can time our time understanding the needs of our patrons and the librarians who will use these new tools. As a next step, we have decided to do research on where this feature can have the most impact and will focus our efforts on enriching a small handful of specific subject pages using Tags. One subject we’re excited to prototype with is ‘Cooking’. The team has been curating the best cooking-related information to showcase using Subject Tags and testing new features to launch alongside Subject Tags. Here is a mockup by Roya, a fellow in our design community, showing one possible UI we have in mind:

When Subject Tags are launched, we hope you can visit the ‘Cooking’ page and provide us with input on what we can improve on and what you would like to explore in a Subject page. With your feedback, librarians will have a better understanding on how to enhance your book exploration process with personally curated topics. Moving forward, we will utilize Subject Tags to enrich other subject pages on the Open Library and slowly phase out the mundane subject pages we have currently.

Ending note

Thank you to the incredible Open Library community for their unwavering support over these past months. A special shout-out goes to Mek, whose mentorship has been nothing short of exceptional. Not only has Mek dedicatedly guided me through the program, but also gone the extra mile to make sure I’ve had the most enriching learning journey. Lastly, my deepest thanks to the Internet Archive and Google Summer of Code for making it possible for me to be a part of this life-changing experience. This is an experience that I’ll never forget.